Public-source method note · Research cutoff: September 20, 2026 · Educational discussion only
A CFO can know the price of a model call and still not know whether an agent workflow is economical.
Token spend is one input. Tool fees are another. But the finance question is usually about a business result: Did the case close? Was the output accepted? Did someone have to rescue it? How much review and rework did it create? Did an exception reopen later?
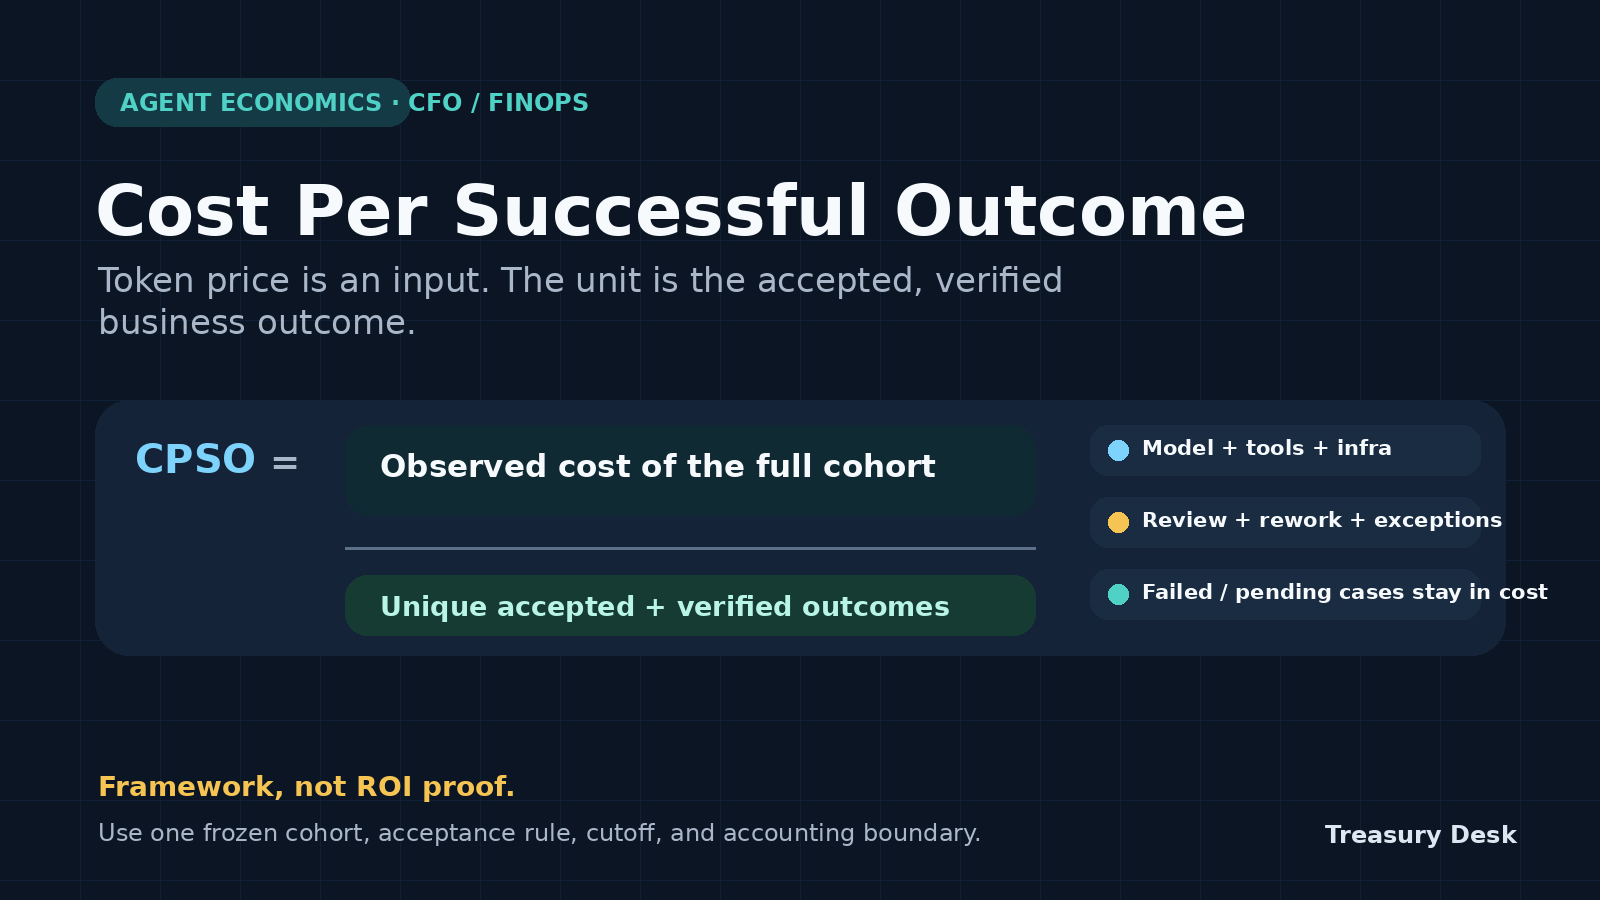
That makes cost per successful outcome, or CPSO, one useful workflow-level unit metric for a defined process. The idea is simple: divide the observed cost of the cohort by the number of unique outcomes that were actually accepted and verified. The discipline is in defining both sides before comparing models, agents, or manual work.
Token price is not outcome cost
The FinOps Foundation distinguishes resource-efficiency unit metrics, such as cost per token, from business unit metrics, such as cost per resolved case. That distinction is especially useful for agent workflows. A low-cost model can be expensive at the workflow level if it generates more retries, more reviewer time, more rework, or more unresolved exceptions. A higher-cost model can have the opposite pattern. Neither result should be assumed in advance.
The CFO therefore needs two connected records:
- execution cost — model, tool, infrastructure, and attributable human work; and
- outcome evidence — whether a unique business case met the pre-defined acceptance test.
Provider usage and cost APIs can supply part of the first record. Traces and telemetry can help join model calls, tool calls, retries, and routing decisions to a workflow. But none of those systems decides whether the business outcome was acceptable. That is a control definition, not a billing field.
Define the unit before comparing cost
Start with one unit: a unique business case or outcome. Not a token. Not an API call. Not an agent step. Not a retry.
Before a comparison, freeze:
- the workflow and scope;
- the cohort and arrival period;
- the complexity mix;
- the cutoff date;
- the acceptance-test version;
- the required reviewer or control;
- the SLA or allowed completion window; and
- the rule for reopened cases.
This matters because agent evaluation is inherently trial-based. Anthropic’s agent-evaluation guidance separates a task, a trial, the transcript, graders, and the final outcome. It also distinguishes measures that improve when more attempts are allowed from measures of repeated reliability. A system that succeeds after three attempts is not economically identical to one that succeeds on the first attempt, even if both eventually pass.
For finance work, the final denominator should therefore be a unique accepted and verified outcome. An agent saying “done” is not enough. The acceptance evidence might be a reconciled record, an approved close task, a validated forecast update, or another workflow-specific proof. The important point is that two qualified reviewers should be able to apply the stated criterion and reach the same disposition with reasonable consistency.
Human-rescued outcomes should be visible rather than hidden. A rescued case can still count as a workflow success if that rule was defined in advance, but the rescue labor belongs in the cost.
The CPSO formula
The following is a Treasury Desk author synthesis, not an accounting rule or an industry standard:
CPSO_observed = C_observed_total_for_cohort / N_unique_accepted_verified_outcomes
The numerator includes known costs for all cases in the cohort up to the cutoff: accepted, rejected, failed, cancelled, reopened, and still pending. Failed attempts do not disappear from the economics just because they disappear from the denominator.
If the cohort is still maturing, label CPSO provisional. Pending cases may generate more future cost or later become accepted outcomes. If there are zero accepted outcomes, CPSO is not calculable / no successful outcomes. It is not zero.
Keep at least three cost views separate:
| View | What belongs in it | What not to do |
|---|---|---|
| Direct / variable | Model usage, tools, infrastructure, attributable review, verification, rework, and exception labor | Do not add retry cost twice if provider usage already includes every attempt |
| Fully loaded | Direct cost plus a disclosed allocation of setup, integration, evaluation, monitoring, maintenance, and governance | State the allocation driver and analysis period; do not present this as accounting capitalization guidance |
| Unknown / unallocated | Missing labor, shared platform cost, incomplete telemetry, or other unquantified items | Missing is not zero |
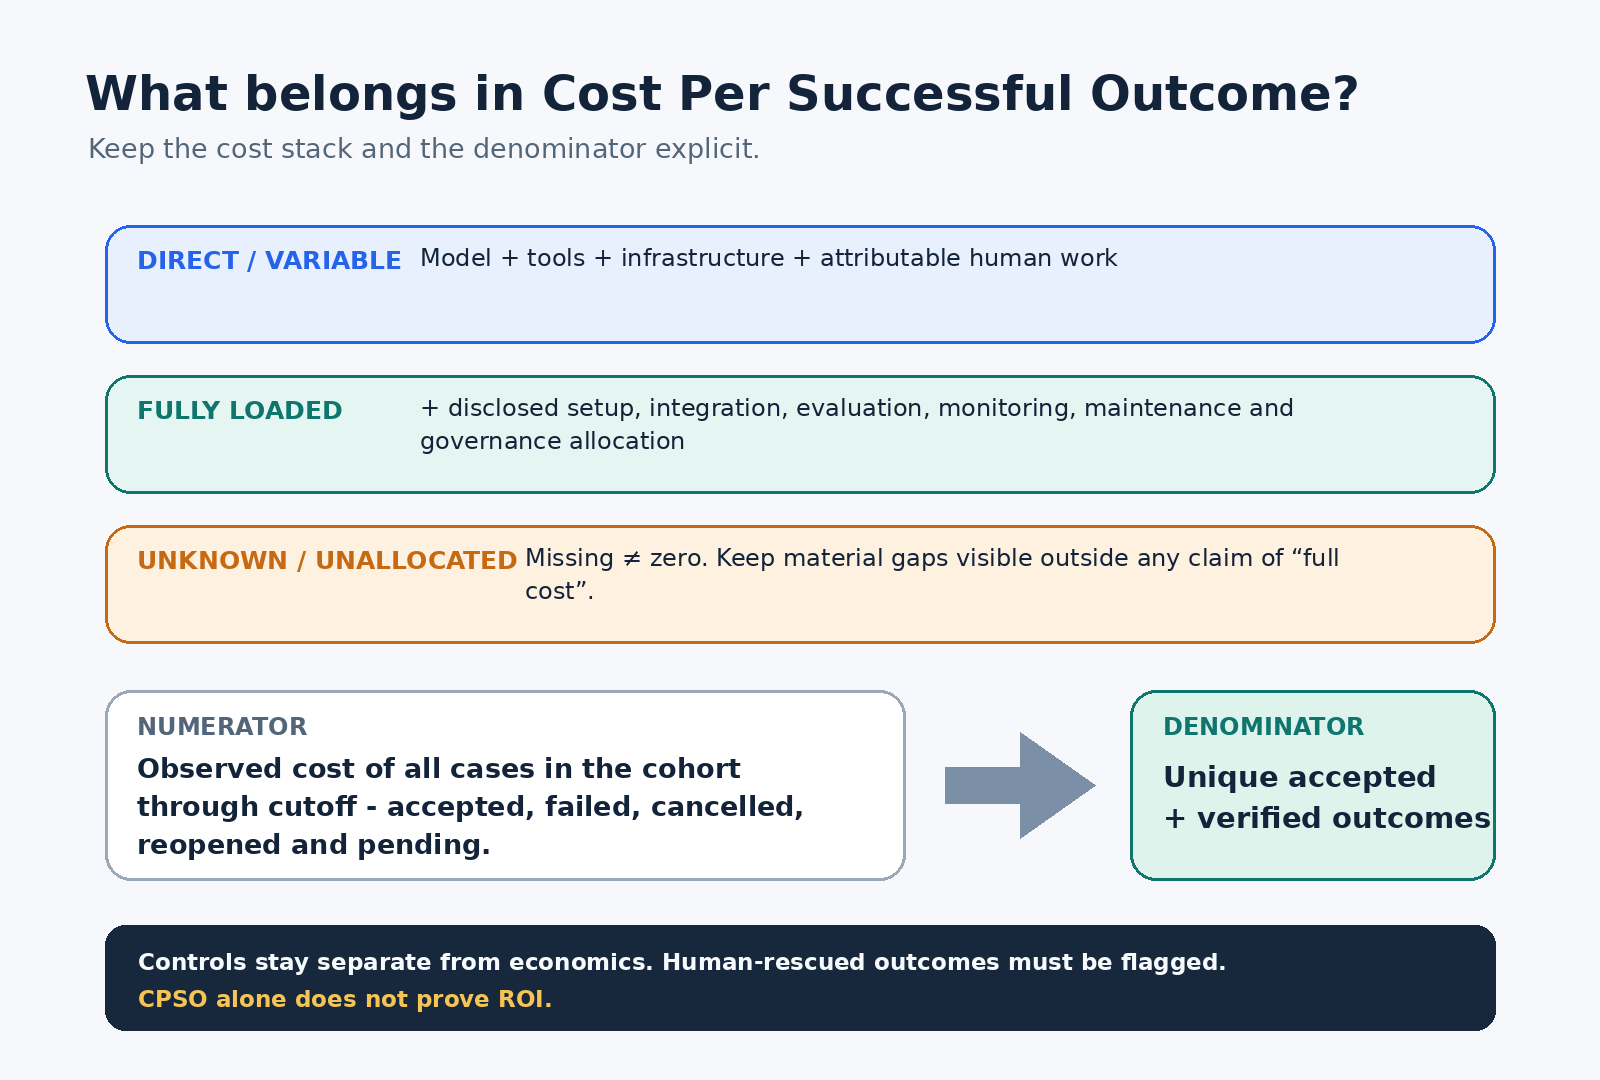
Also keep actual cost, estimate/scenario, and hypothetical risk loss in separate columns. A scenario is useful for planning. It is not an observed fact.
Synthetic example A: cheaper inference can lose through rework
The numbers below are synthetic author-specified inputs, not a benchmark, current provider price, or client case. Both variants process 100 comparable cases with the same acceptance test and control boundary. Labor is valued at a synthetic $90/hour solely to make the arithmetic transparent.
| Synthetic metric | Economy agent | Higher-cost agent |
|---|---|---|
| Accepted outcomes | 72 / 100 | 88 / 100 |
| Average attempts per case | 2.40 | 1.35 |
| Human-rescue rate | 25% | 10% |
| Reopen rate | 12% | 4% |
| Model cost for cohort | $30 | $240 |
| Review + rework + exception labor | $3,660 | $1,470 |
| Direct cohort cost | $3,790 | $1,810 |
| Direct CPSO | $52.64 | $20.57 |
| Allocated setup/eval/monitoring | $900 | $1,150 |
| Fully loaded CPSO | $65.14 | $33.64 |
The allocation is synthetic and explicit: setup/evaluation/monitoring cost is spread over the 100 initiated cases in the analysis period. An unquantified security/governance opportunity-cost bucket remains unknown rather than being set to zero.
In this synthetic scenario, the variant with eight times the model spend still has the lower CPSO because reviewer, rework, and exception labor falls sharply. That is not evidence that expensive models are generally cheaper. It is evidence that model price alone is an incomplete decision variable.
Synthetic example B: the premium option does not justify its extra cost
Now change the workload. Assume the cases are more routine and both variants already perform well under the same acceptance rule.
| Synthetic metric | Economy agent | Premium agent |
|---|---|---|
| Accepted outcomes | 94 / 100 | 96 / 100 |
| Average attempts per case | 1.20 | 1.12 |
| Human-rescue rate | 6% | 4% |
| Reopen rate | 3% | 2% |
| Model cost for cohort | $55 | $420 |
| Review + rework + exception labor | $1,032 | $826.50 |
| Direct cohort cost | $1,172 | $1,351.50 |
| Direct CPSO | $12.47 | $14.08 |
| Allocated setup/eval/monitoring | $600 | $1,300 |
| Fully loaded CPSO | $18.85 | $27.62 |
The premium variant produces two additional accepted outcomes, but the scenario does not assign those outcomes higher economic value. On the stated unit-cost boundary, the premium option has the higher CPSO. That still does not establish negative ROI. ROI requires a separate value model, cash-flow assumptions, timing, and a counterfactual.
These two examples are why a CFO should ask for a sensitivity table rather than a single “AI cost” number. The result can change with success rate, attempts, review minutes, exception frequency, volume, and allocation policy.
Comparability comes before optimization
Manual, hybrid, and agent-assisted workflows are only comparable when they use the same business scope, difficulty mix, acceptance criteria, control requirements, SLA, and cost boundary.
A useful comparison table includes:
- success rate;
- human review rate;
- human rescue rate;
- reopening rate;
- attempts or routing pattern;
- direct and fully loaded CPSO;
- latency distribution, not just an average;
- coverage: what share of eligible cases the workflow actually handles; and
- unknown or unallocated cost.
Controls should not be silently traded away to improve the average. If a workflow requires a second review, segregation of duties, a reconciliation proof, or another mandatory safety gate, that requirement belongs in every compared variant.
Negative evidence also belongs in the decision pack. METR’s 2025 randomized study found that experienced open-source developers using then-current AI tools took longer in that specific setting, and the authors explicitly cautioned against broad generalization. The useful lesson for finance is not the 19% figure. It is that productivity effects can reverse under a different task, user, tool, or measurement design. Measure the workflow you actually operate.
Instrumentation: connect spend to the case
The practical challenge is joining execution data to the outcome record without turning observability into a surveillance system.
OpenAI’s agent-evaluation documentation uses traces to capture model calls, tool calls, guardrails, and handoffs. OpenTelemetry’s GenAI semantic conventions provide attributes for agents, workflows, models, tools, and token usage. Provider billing APIs can supply actual usage and cost data. Those layers can support a join such as:
cohort ID → outcome ID → attempt ID → trace/tool records → cost records → acceptance evidence
The join needs stable identifiers and privacy minimization. Prompt and output content may contain sensitive data; cost attribution does not require copying every prompt into a finance ledger.
Vendor material can be useful as a signal of where tooling is moving, but it should stay attributed. RadiantOps’ current launch and product materials say it surfaces agent-related cost and rework information alongside work records. That illustrates an instrumentation direction; it is not independent evidence that the product improves ROI or that the same measures transfer to a finance workflow.
The Agent Outcome Cost Record
A CFO-friendly operating artifact can be small. The Agent Outcome Cost Record should collect the minimum evidence needed to reconstruct one case and roll it into a cohort:
- workflow, cohort, and outcome IDs;
- scope and success-definition version;
- arrival period and cutoff;
- attempts and routing;
- model/tool/infrastructure cost sources and units;
- review, rework, and exception labor with rate provenance;
- allocated cost and allocation driver;
- unknown/unallocated items;
- acceptance evidence and required reviewer/control;
- human rescue flag;
- rejection, pending, cancellation, reopen, and exception status;
- owner and review date.
The record collects evidence; it does not certify the result. Acceptance still depends on the workflow’s control owner and evidence rule.
Download the Agent Outcome Cost Record template. The workbook provides an outcome-record table, cohort CPSO summary, comparability checklist and a clearly labeled synthetic example. It is an evidence-collection template, not an accounting rule, audit opinion or proof of ROI.
What the CFO should ask in the review
A useful internal review can start with seven questions:
- What is the unique business outcome we are buying?
- What exact evidence makes it accepted rather than merely completed?
- Are failed and pending cases still inside the cost numerator?
- Are retries already inside provider usage, or are we accidentally charging them twice?
- How many reviewer, rework, rescue, and exception minutes are attributable to the cohort?
- Which costs are allocated, which are unknown, and what allocation driver was used?
- Is the comparison using the same scope, difficulty, controls, and SLA?
If those answers are missing, a precise token-cost dashboard can still produce a weak business case.
Limitations
CPSO is a measurement method, not a guarantee of savings. It does not prove cash savings, capacity release, cost avoidance, productivity, or ROI. Those are separate claims with separate evidence requirements.
CPSO can also be gamed if teams narrow the acceptance test, exclude difficult cases, move human work off the ledger, or compare cohorts with different complexity. Cohort governance and versioned success definitions matter as much as the formula.
Finally, fully loaded cost is a management-analysis view here, not accounting advice. Finance teams should apply their own accounting policies and qualified judgment to capitalization, expense recognition, transfer pricing, or other formal treatment.
A calm next step
Pick one bounded workflow. Freeze the outcome definition and cohort before changing the model. Capture the first month of attempts, provider/tool cost, review/rework time, exceptions, and accepted outcomes. Then compare CPSO across variants without changing the acceptance bar.
That will not tell you whether “AI is worth it” in the abstract. It will answer a better CFO question: what did this workflow cost per accepted, verified outcome — and which part of that cost can we actually change?
Sources and notes
- FinOps Foundation, Unit Economics — unit-economics framing and business-vs-resource unit distinction; retrieved 2026-09-20.
- FinOps Foundation, Unit Economics Playbook: Calculate the Unit Cost — scope, allocation, metric-definition sequence; retrieved 2026-09-20.
- Anthropic, Demystifying evals for AI agents — agent task/trial/outcome and reliability/evaluation framing; published 2026-01-09, retrieved 2026-09-20.
- OpenAI, Evaluate agent workflows and Organization Usage / Costs — trace/eval and raw cost-source examples; retrieved 2026-09-20.
- Anthropic, Usage and Cost API — raw provider usage/cost-source example; retrieved 2026-09-20.
- OpenTelemetry, GenAI semantic conventions — execution/agent/workflow telemetry fields; retrieved 2026-09-20.
- METR, Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity — bounded negative result and transferability caution; published 2025-07-10, retrieved 2026-09-20.
- RadiantOps, press / launch material — vendor-attributed instrumentation example only; published 2026-09-16, retrieved 2026-09-20.
- Treasury Desk, The Exception Queue Is a Training Set for Automation – But Only After Adjudication — adjacent predecessor method; current article is about measurement/unit economics rather than exception adjudication.
- Treasury Desk methodology: How Treasury Desk grounds data, freshness and public-source analysis.
All numerical scenarios in this article are synthetic author-specified illustrations, not client data, provider pricing, benchmarks, or observed Treasury Desk results. Educational public-source analysis; not investment, legal, tax, accounting, or compliance advice.